How to Get Your Site Into ChatGPT and Perplexity Answers
 Bret Siers
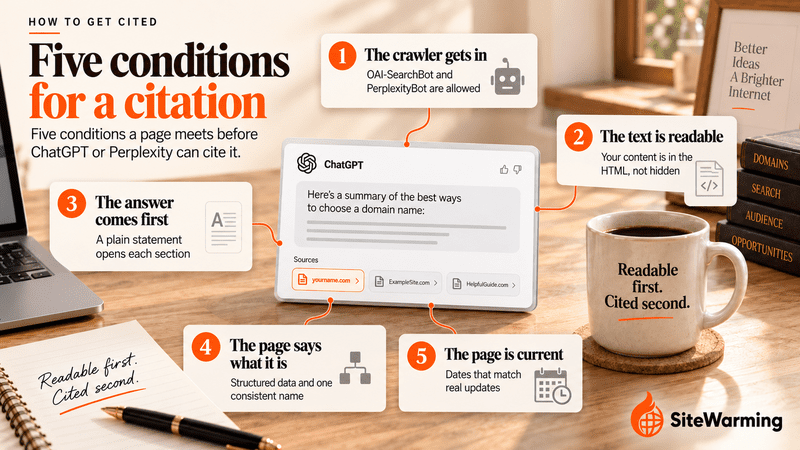
To get your site cited in ChatGPT and Perplexity, let their search crawlers in, write answer-first paragraphs, add clear structured data and keep pages dated and current. ChatGPT search uses OAI-SearchBot and Perplexity uses PerplexityBot, and neither can cite a page it cannot reach. No one can guarantee a citation, but these steps remove the common blockers.
By Bret Siers, founder of SiteWarming. Figures, bot names and settings in this guide were checked on October 8, 2026.
Picture a customer who asks ChatGPT for a recommendation in your category before they find you. Your business isn't in the answer. Three competitors are. The customer picks one, is disappointed, and eventually finds you through a friend. You kept the customer, but the question stays with you: why weren't you in the answer?
The common explanations are that AI favors big brands, or that the placements are paid. Neither is the real cause. Those three competitors had built sites that machines could read: structured data, FAQ schema, a clear entity and direct answer paragraphs. Your site may have four years of real content and none of that machine-facing setup. This guide gives you a concrete set of steps, not another reminder to "create great content."
Why does the usual advice about getting cited fail?
Most guides say to write comprehensive, high-quality content, build authority and publish helpful resources. That advice isn't false, but it doesn't tell you what to change. The gap is usually whether machines can reach and parse your content.
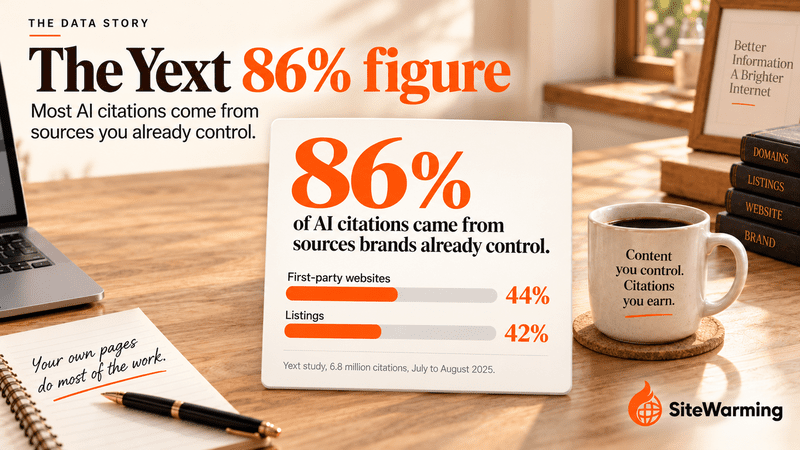
A Yext study of 6.8 million AI citations across ChatGPT, Gemini and Perplexity, collected between July 1 and August 31, 2025, found that 86% came from sources brands already control: first-party websites at 44% and listings at 42%. Yext sells software in this area, so read it as a vendor study. The useful point is the direction. Most citations come from pages an organization controls, so what you can change is whether a crawler can reach your page, whether the text is clear, and whether the page says who you are. What GEO is, and what the research behind it found, is in what is GEO.
How do ChatGPT search and Perplexity find your site?
The two systems use different crawlers, so the fixes differ.
OpenAI's ChatGPT search help page says ChatGPT search sometimes partners with other search providers, rewrites your question into targeted queries, and ranks results using multiple factors. It says sites become eligible by allowing OAI-SearchBot to crawl them and by letting traffic from OpenAI's published search-bot IP addresses reach your host or CDN, and it adds that placement is not guaranteed. The page does not say which providers it uses or how.
Perplexity documents its own crawler: PerplexityBot is designed to surface and link websites in Perplexity search results, and is not used to crawl content for AI foundation models. A second agent, Perplexity-User, visits a page when a user's question calls for it.
| Bot | Operator | What it does | What blocking it affects |
|---|---|---|---|
| OAI-SearchBot | OpenAI | Surfaces sites in ChatGPT search | The site is not shown in ChatGPT search answers, though it can still appear as a navigational link |
| ChatGPT-User | OpenAI | Visits a page when a user asks ChatGPT or a custom GPT | User-initiated, so robots.txt rules may not apply; it is not used to decide whether content appears in Search |
| PerplexityBot | Perplexity | Surfaces and links sites in Perplexity search results | Reduces your appearance in Perplexity results |
| Perplexity-User | Perplexity | Visits a page when a user's question calls for it | It generally ignores robots.txt, because a user requested the fetch |
OpenAI's separate GPTBot crawls content that may be used to train its models, and blocking it does not affect search visibility. For Anthropic's bots and the full list, see the machine-readable website guide.
What are the five steps to get cited in ChatGPT and Perplexity?
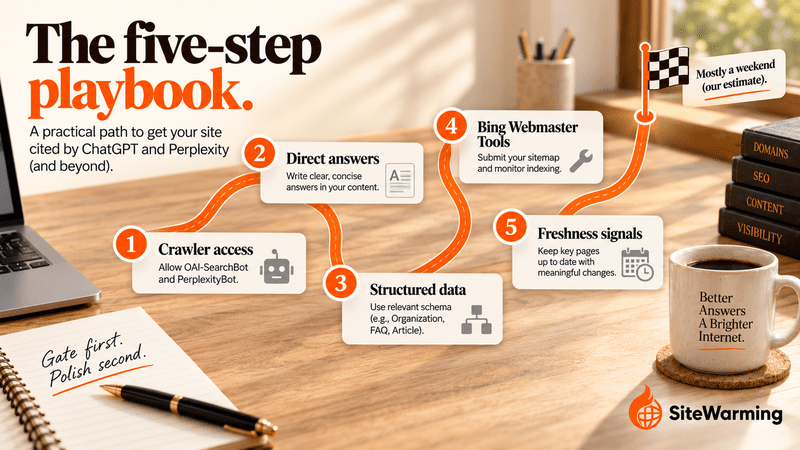
Five steps, in the order that matters. Crawler access comes first, because nothing else counts if the bot cannot reach the page. We estimate the baseline work takes about a weekend.
| Step | What you do | What it fixes |
|---|---|---|
| 1. Verify crawler access | Let OAI-SearchBot and PerplexityBot in at robots.txt, your CDN and your host | The page is reachable |
| 2. Write direct answer paragraphs | Open each section with a plain statement | The page is quotable |
| 3. Add structured data | Add Organization, Article, FAQPage and BreadcrumbList JSON-LD | The page says what it is |
| 4. Set up Bing Webmaster Tools | Verify the site and submit the sitemap | You can see how a major index sees you |
| 5. Add freshness signals | Add datePublished, dateModified and a visible update note | The page shows when it was checked |
Step 1: How do you check that AI crawlers can reach your site?
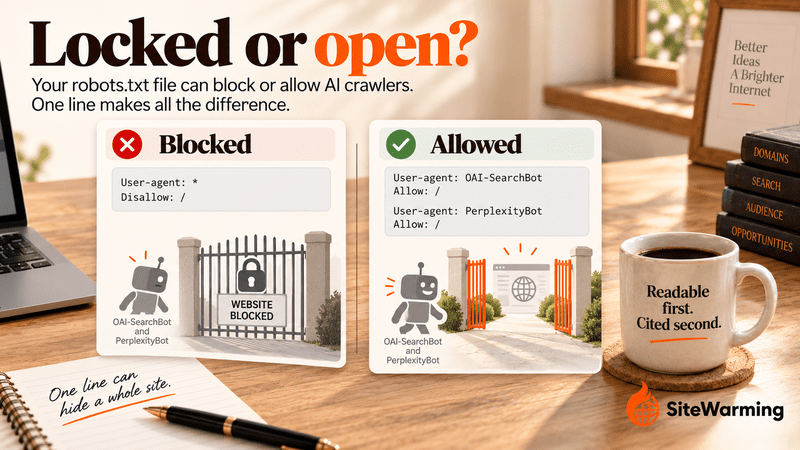
Open yoursite.com/robots.txt, a file most owners never look at. Look for rules like these:
User-agent: OAI-SearchBot
Disallow: /

User-agent: PerplexityBot
Disallow: /

User-agent: *
Disallow: /
The first two block the search bots that matter here. The last blocks every crawler, which is often a leftover from a staging site. If you want to be cited, remove any of these and, if you like, state the permission explicitly:
User-agent: OAI-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /
Blocking GPTBot or ClaudeBot is a separate decision about model training and does not remove you from ChatGPT search, so don't treat those lines as the same problem. Changes to these rules can take up to about 24 hours to apply, according to the OpenAI and Perplexity documentation. Perplexity also recommends allowing its published IP ranges.
Robots.txt is not the only gate. Check your CDN and firewall too. Cloudflare's documentation says its older Block AI bots setting blocks verified bots classified as crawling for AI training, that it was being deprecated on September 15, 2026, and that new defaults for new domains from that date block Training and Agent bots on pages with ads while leaving Search allowed. Dashboards change, so confirm that no rule is blocking OAI-SearchBot or PerplexityBot in whatever yours shows today. One more detail from OpenAI's publisher FAQ: a page you disallow can still surface as a link and title, and the way to prevent that is a noindex tag, which only works if the page is crawlable. For how crawlers decide what to fetch, see how AI crawlers decide what to index.
Step 2: How do you write direct answer paragraphs?
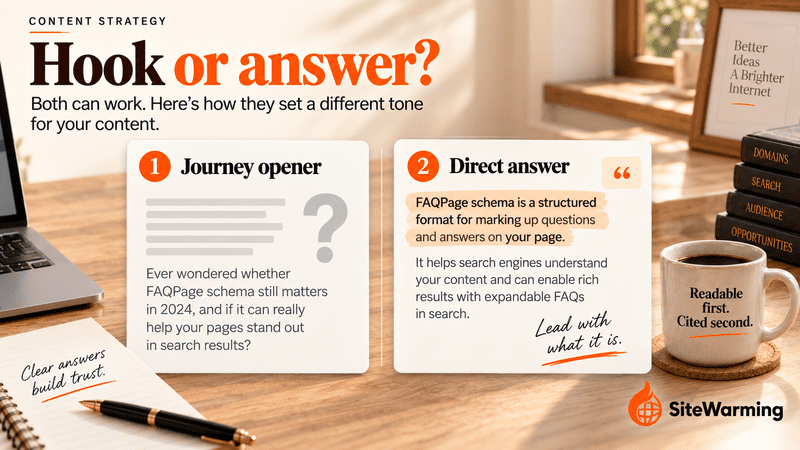
Open each major section with one or two plain sentences that state what the section covers. Machines extract and summarize statements, so a clever hook works against you. Compare two openings for a section about FAQ markup.
The weak opening: "Ever wondered whether the technical details of schema really matter? Let's take a journey through the world of structured data." The strong opening: "FAQPage schema is a structured format for marking up question-and-answer pairs so that machines can extract them." The second is something a system can quote whole.
You don't have to choose between your two audiences. Lead with the direct statement, then add the narrative and the human voice below it. This guide opens that way.
Step 3: What structured data should you add?
Structured data is markup that tells machines what a page is, who made it and what kind of content it holds. Add four types in JSON-LD, each on specific pages:
| Type | Where it goes | What it states |
|---|---|---|
| Organization | Homepage | Your entity: name, URL and contact route, so systems identify you the same way each time |
| Article or BlogPosting | Every content page | The content type, author, publication date and modification date |
| FAQPage | Pages that answer questions | Ready-made question-and-answer pairs |
| BreadcrumbList | Interior pages | Where each page sits in the site |
Put the JSON-LD in the page head and validate it with Google's Rich Results Test, since Google warns that invalid markup can make a page ineligible for rich results. Templates and code for each type are in schema markup for small websites, and the minimum a new domain needs is in what structured data a domain needs before launch. For the audit that ties these together, use the machine-readable website guide.
Be realistic about what this does. Google says there is no special schema.org structured data you need to add for its AI features, and the OpenAI and Perplexity crawler pages we read list crawler access, not structured data, as the requirement. Schema is clarity, not a switch. Also note that Google stopped showing FAQ rich results on May 7, 2026, so use FAQPage only where the questions and answers are visible on the page. How machines judge a domain beyond markup is covered in how AI search engines decide which domains to trust.
Step 4: Should you set up Bing Webmaster Tools?
Yes, as a low-cost hedge. Bing Webmaster Tools is free. Verify your site, submit your sitemap, and compare the number of pages Bing has indexed with the number Google has. Suppose, hypothetically, Bing has indexed 10% of your pages while Google has indexed 90%. That gap would be a visibility problem for any system that draws on Bing's index.
To be precise: OpenAI's help page says ChatGPT search sometimes partners with other search providers and doesn't say which, so we can't tell you Bing is required. Our advice is that a free tool that shows how a second major index sees you is worth ten minutes.
Step 5: How do you add freshness signals?
Include both datePublished and dateModified in your Article schema, and update the modified date whenever you really revise a page. For key evergreen pages, add a visible note near the top, such as "Updated October 2026." We haven't found a vendor that documents freshness as a citation factor, so treat this as our view: dates cost minutes, help readers judge currency, and make it obvious that the page is maintained. Never change a date without changing the content.
How do you check that AI can read your site?
After the five steps, run four checks.
- Run Google's Rich Results Test to confirm your schema is detected without errors.
- Confirm in Bing Webmaster Tools that your sitemap is submitted and your pages are indexed.
- Review your robots.txt by hand to make sure OAI-SearchBot and PerplexityBot aren't blocked, then check your CDN settings.
- Ask ChatGPT with search on, or Perplexity, a question your site should answer, and see whether you appear.
The last test isn't comprehensive, but it shows whether machines find you for your core topic. If they don't, why AI search engines ignore most websites lists the specific failures to check.
How do you monitor your citation rate?
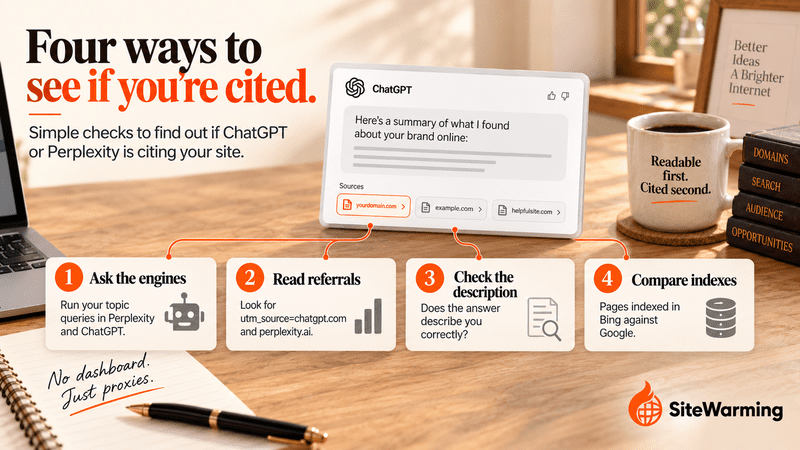
There is no official AI citation dashboard, so use proxies.
- Run topic-related queries in Perplexity regularly and note whether your site is cited.
- Check analytics for traffic from ChatGPT. OpenAI says ChatGPT adds utm_source=chatgpt.com to referral URLs, so publishers that allow OAI-SearchBot can see it in tools such as Google Analytics. Also look for perplexity.ai in your referral report.
- Search your organization name in Perplexity and ChatGPT and read how you're described. If the description is wrong or differs from what your site says, you likely have entity confusion.
- Compare indexed page counts in Bing Webmaster Tools and Google over time.
What can you honestly promise?
Getting cited is neither a one-time project nor an endless grind. The baseline work, which is crawler access, structured data and Bing indexing, is one focused effort, and we estimate it takes about a weekend. The ongoing work, which is freshness, direct answers and FAQ sections, amounts to good content habits.
It is not a guarantee. OpenAI's help page says placement is not guaranteed, and its guidelines are about making content discoverable and clearly cited, not about promising a spot. The Yext data points the same way: the organizations that get cited aren't doing anything exotic. They tell machines who they are and what they do, and they make sure crawlers can reach them. The gap is smaller than most people assume.
But it is a gap you can close, and the next customer may not find you through a friend. For the strategy behind this, see how to optimize for both Google and AI search.
The SiteWarming perspective. A page can only be cited if a machine can find something readable on it. A warm site from SiteWarming launches with DNS configuration, an HTTPS certificate, hosting, structured story data, AI-readable FAQs and a protected contact path, so a domain you haven't built yet still gives crawlers something clear to read. That is groundwork, not a guarantee of citation. See how SiteWarming works, what SiteWarming is, whether a domain with no content can show up in AI search, how to make a domain discoverable without a website, or start free.
Frequently asked questions about getting cited in ChatGPT and Perplexity
How do I get my website cited in ChatGPT?
Let the search crawlers in, then make the page easy to quote. Allow OAI-SearchBot for ChatGPT search and PerplexityBot for Perplexity, open each section with a plain answer, add structured data, and keep dates accurate. OpenAI says placement isn't guaranteed, so the goal is to remove blockers, not to buy a spot.
Does ChatGPT use Bing?
OpenAI's help page says ChatGPT search sometimes partners with other search providers, and it doesn't name Bing or explain how any provider is used. Sites become eligible by allowing OAI-SearchBot. Bing Webmaster Tools is free, so verifying your site there is a cheap hedge, but OpenAI doesn't list it as a requirement.
Should I allow OAI-SearchBot?
Yes, if you want to appear in ChatGPT search. OpenAI says sites that opt out of OAI-SearchBot won't be shown in ChatGPT search answers, though they can still appear as navigational links. Also let OpenAI's published search-bot IP addresses reach your host or CDN, and allow up to about 24 hours for robots.txt changes.
Does blocking GPTBot stop ChatGPT from citing me?
No. GPTBot crawls content that may be used to train OpenAI's models, and OpenAI says blocking it doesn't affect search visibility. ChatGPT search relies on OAI-SearchBot, which is a separate crawler. Decide the two independently: block GPTBot to opt out of training, and allow OAI-SearchBot if you want to be cited.
How do I get into Perplexity answers?
Allow PerplexityBot, which Perplexity says is designed to surface and link websites in its search results and isn't used to crawl content for AI foundation models. Perplexity recommends allowing its published IP ranges too. Then make your pages clear and quotable. Perplexity-User, which fetches pages when a user asks, generally ignores robots.txt.
Can I guarantee a citation?
No. Nobody can guarantee a citation. OpenAI says placement isn't guaranteed, and its guidance is about making content discoverable and clearly cited. You can remove blockers, make pages readable and quotable, and measure results, but whether a system cites you depends on the question, the competing pages and the engine.
How do I track traffic from ChatGPT?
Filter your analytics for utm_source=chatgpt.com. OpenAI says ChatGPT adds that parameter to referral URLs, and publishers that allow OAI-SearchBot can see the traffic in tools such as Google Analytics. For Perplexity, look for perplexity.ai in your referral report and run your topic queries there by hand.
Related reading
- What Is GEO? A Guide to Generative Engine Optimization in 2026: the definition and the research behind it.
- The Beginner's Guide to Making Your Website Machine-Readable: the 30-minute audit and the full crawler table.
- Schema Markup for Small Websites: Do You Actually Need It?: the five types with code.
- What Structured Data Should Every Domain Have Before Launch?: the minimum for a new domain.
- Why AI Search Engines Ignore Most Websites (And What to Do About It): six failures to check.
- How to Optimize Domains for Both Google and AI Search: the two-audience strategy.
Share this article
Ready to Transform Your Domain Portfolio?
Start building real value with your domain investments today.