Why AI Search Engines Ignore Most Websites (And What to Do About It)
 Bret Siers
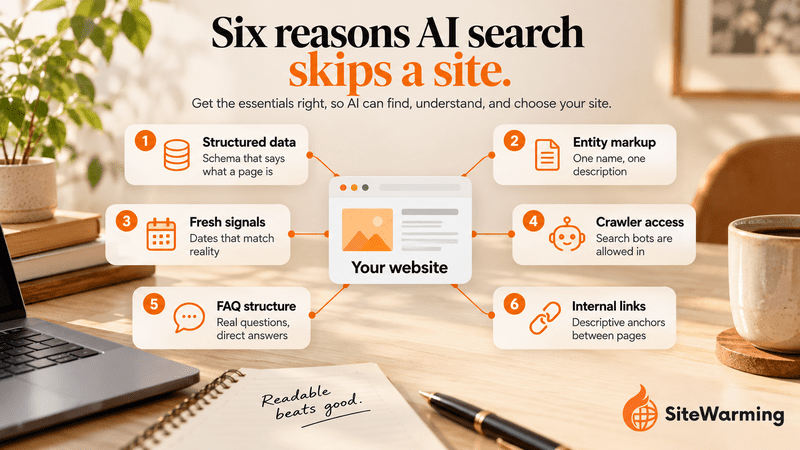
AI search engines ignore most websites because they can't read them, not because the content is weak. Six failures cause most of it: missing structured data, inconsistent entity names, stale date signals, blocked crawlers, no FAQ structure and unclear internal links. Each is fixable, and the 30-day plan below fixes them in order.
By Bret Siers, founder of SiteWarming. Facts and dates in this guide were checked on October 9, 2026.
Nobody tells you this when you're building a website: the machines decide whether you exist before any human ever visits. I've watched it happen to sites I respected, built by people with real expertise and years of work behind them.
Then someone asks Perplexity a question one of those sites should be answering, and the answer cites three other sources. That isn't a visibility problem. It isn't a content problem. It's a readability problem, and readability is the part you can fix.
Why do AI search engines ignore most websites?
An AI search engine can only use a page it can fetch, read and tie to an identifiable source. A site that fails any of those three steps gets skipped, however good the writing is. The six failures below are the ways that happens, ordered from the technical to the editorial.
Why isn't great content enough?
"Create great content" isn't advice. It tells you what to want without telling you what's wrong. A page can be excellent and still be unreadable to a machine, and that gap is where most sites sit.
Two different systems are involved, and they fail in different ways. Training data is what a model learned before its cutoff. Live retrieval is what a search crawler fetches when someone asks a question today. Here is what is documented for each.
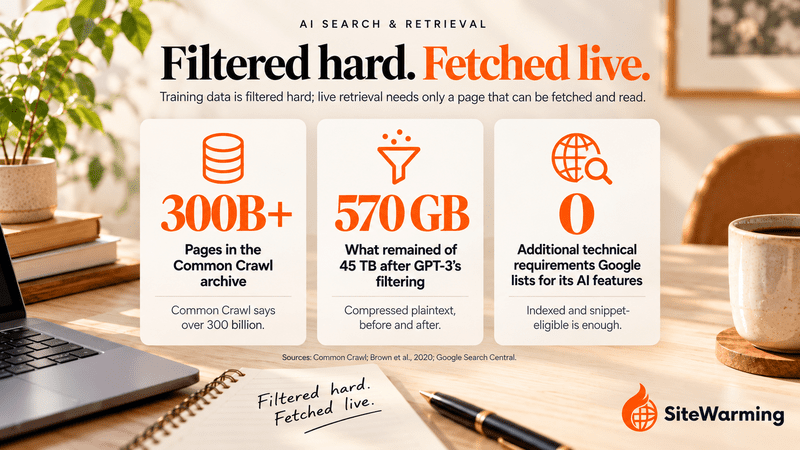
Training data. Common Crawl says its archive holds over 300 billion pages. Model builders don't train on it raw. The Mozilla Foundation's 2024 report says they choose from filtered versions, and that the filtering techniques it examined were simplistic and often focused on removing pornography. The GPT-3 paper documents one case: 45TB of compressed plaintext before filtering and 570GB after, using similarity to high-quality reference corpora and fuzzy deduplication. That is about 1.3 percent by volume (our arithmetic), it counts bytes, not pages, and other labs filter differently. Our view is that what survives tends to be parseable, original and substantial, but no lab publishes its full filter. The mechanism is covered in why AI can't read your parked domain.
Live retrieval. OpenAI says OAI-SearchBot is used to surface websites in ChatGPT search. Perplexity says PerplexityBot is designed to surface and link websites in its search results. Google says a page must be indexed and eligible to be shown in Search with a snippet to appear in AI Overviews and AI Mode, and that there are no additional technical requirements. This is the side you can change this month, and it is what the six failures are about.
What are the six data failures that make a site invisible to AI search?
Each failure is structural, and each has a fix. Use this table to find the ones that apply to you, then read the matching section.
| Failure | What it looks like | How to check | The fix |
|---|---|---|---|
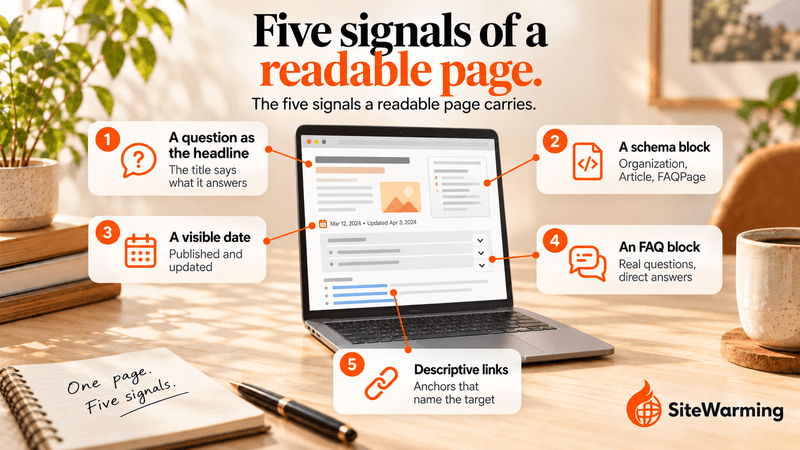
| 1. No structured data | A crawler gets text but not what the page is or who made it | Paste the URL into Google's Rich Results Test and the Schema Markup Validator | Add Organization, Article and FAQPage JSON-LD |
| 2. No entity markup | The same organization appears under different names | Search your own name variants across the site, schema and social profiles | Pick one name and one description and use them everywhere |
| 3. Stale content signals | Old dates, or none | Compare the visible date with dateModified in your schema | Add datePublished and dateModified, and update them when the content really changes |
| 4. Blocked crawlers | A Disallow rule, a firewall or a bot-blocking toggle | Open yourdomain.com/robots.txt and check your CDN settings | Allow the search bots you want to be cited by |
| 5. No FAQ structure | Answers buried in long paragraphs | Scan your headings for question-style headings | Add three to five real questions with FAQPage markup |
| 6. Unclear internal linking | Key pages with no links in, or vague anchors | List pages with no internal links; read each anchor out of context | Link related pages with descriptive anchor text |
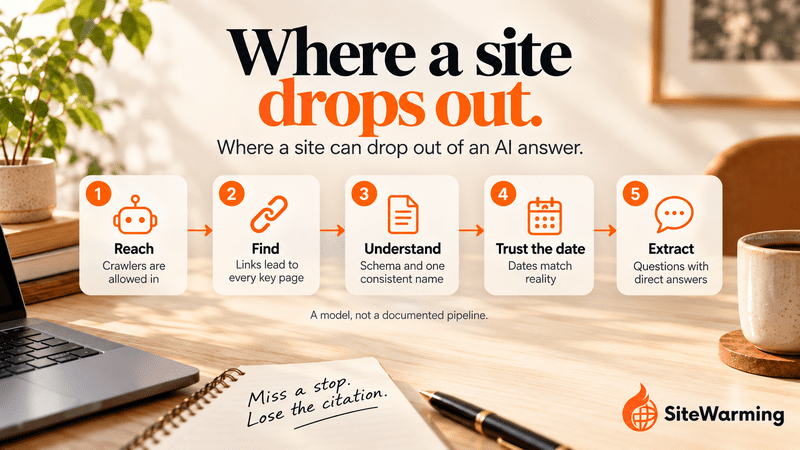
We think of the six as stops on one path, from a crawler reaching a page to an answer quoting it. That order is our model, not a documented pipeline, but it is a useful way to find where your site drops out.
Failure 1: Is missing structured data hiding your site from AI?
Structured data is JSON-LD that tells a machine what a page is and who made it. Without it, a crawler has the text and has to infer the rest. That is a disadvantage, but it isn't the whole story, and two sources say different things.
Google says there is no special schema.org structured data you need to add to appear in AI Overviews or AI Mode. On the other side, Search Engine Land reported on March 20, 2025 that Microsoft's Fabrice Canel said at SMX Munich that Microsoft uses schema markup to help its LLMs understand content. Our view is that schema is a cheap way to remove ambiguity, not a ranking switch, so we add three types and keep them honest:
- Organization on the home page, naming who runs the site.
- Article on every post, with the author and dates.
- FAQPage on any page with a visible question-and-answer section.
The markup must describe what is visible on the page. Check each page with Google's Rich Results Test and the Schema Markup Validator. For a small site this is usually an afternoon's work (our estimate). The platform steps are in schema markup for small websites, and what structured data a domain needs before launch covers a domain with no site yet. For the wider checklist, see the beginner's guide to making your website machine-readable.
Failure 2: Why does an inconsistent organization name hurt AI citations?
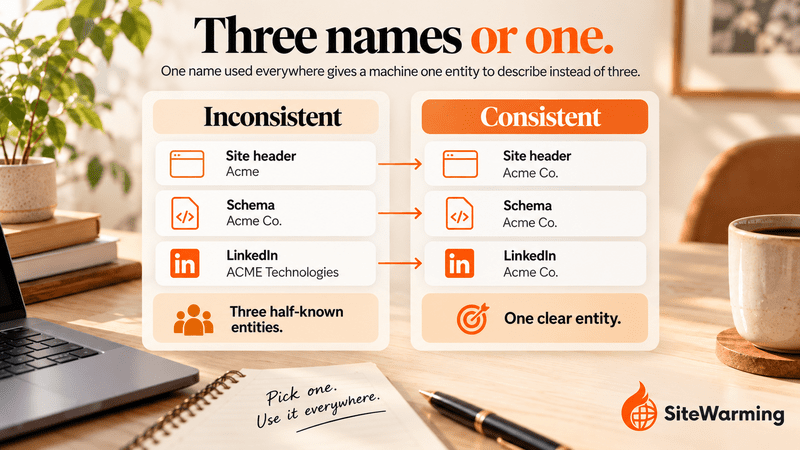
A machine decides whether two mentions are the same thing by comparing names and descriptions. If your site says "Acme", your schema says "Acme Co." and your LinkedIn page says "ACME Technologies", a machine has three half-known entities instead of one clear one. The cost is a weaker, less consistent picture of you, and that picture is what a citation draws on.
Google's Organization documentation says to use the same name and alternateName that you use for your site name, and says the markup helps Google disambiguate your organization. No AI vendor documents an entity graph, so treat the wider benefit as our view. The fix costs nothing:
- Choose one exact organization name.
- Write one description of what you do, in one or two sentences.
- Use both in your header, About page, schema, author bios and social profiles.
- List the profiles that are really yours in sameAs.
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "name": "Acme Co.",
  "alternateName": "Acme",
  "url": "https://www.example.com/",
  "description": "One sentence on what Acme Co. does and who it serves.",
  "sameAs": ["https://www.linkedin.com/company/acme-co/"]
}
Failure 3: Do stale dates stop AI search from citing a page?
Recency matters to systems that answer questions about the present. Search Engine Land's report of the SMX Munich remarks quotes Canel saying "Gen AIs value fresh content in particular, partly as a reference check of their LLM training data". That is one reported remark about one company, not documentation for every engine, but it is a reason to make dates honest and visible.
Google's Article documentation lists datePublished and dateModified as recommended properties in ISO 8601 format, and recommends including timezone information. Four rules keep the signal clean:
- Show the published date and, where it applies, an updated date on the page.
- Put the same dates in your Article schema.
- Change dateModified only when the content has really changed.
- On evergreen pages, add a short "checked on" line stating when the facts were last verified.
{
  "@context": "https://schema.org",
  "@type": "Article",
  "headline": "Your Article Title",
  "datePublished": "2026-06-19T09:00:00-05:00",
  "dateModified": "2026-10-09T09:00:00-05:00",
  "author": { "@type": "Person", "name": "Your Name" }
}
Failure 4: Are you accidentally blocking AI search crawlers?
Security plugins, CDN settings and "block AI scrapers" toggles can all stop an AI crawler without you ever editing robots.txt. A blocked crawler can't read your page, so it can't cite it. The part that trips people up is which bot matters.
OpenAI documents OAI-SearchBot as the crawler for ChatGPT search and GPTBot as the crawler for training, so blocking GPTBot doesn't remove you from ChatGPT search, and allowing only GPTBot doesn't put you in it. Perplexity recommends allowing PerplexityBot in robots.txt if you want your site in its results. The host matters too: Cloudflare's July 1, 2026 changelog says that from September 15, 2026, new domains onboarding to Cloudflare get defaults that block Training and Agent bots on pages that display ads and keep Search allowed. Check four places:
- Your robots.txt, for a Disallow rule under "User-agent: *" or under a search bot you want.
- Your CDN or firewall, for bot-blocking and AI-crawler settings.
- Your security plugin, for "block AI scrapers" options.
- Your page source, to confirm the text is in the HTML. Vercel's analysis found that OpenAI, Anthropic and Perplexity crawlers fetch JavaScript files but don't run them, so a page that builds its text with JavaScript can look empty to them.
The full bot-by-bot table is in how AI crawlers decide what to index.
Failure 5: Does an FAQ section help AI search?
A question followed by a short, direct answer is easy for any system to lift whole. No vendor documents a preference for that format, so that part is our view, and it's a view we act on because the cost is low and readers like it too. Google stopped showing FAQ rich results starting May 7, 2026, so the markup no longer earns a rich result there. We still add FAQPage markup beside a visible FAQ because it describes the page accurately and costs a few lines.
Three to five questions per page is enough, and they should be real. Take them from your Search Console queries, your support inbox, your sales calls and the People Also Ask box, not from a guess. Answer each in two or three sentences that make sense without the page around them, and make the markup match the visible text exactly. For the broader picture of how a page gets quoted, see how to get your site into ChatGPT and Perplexity answers.
Failure 6: How does internal linking affect AI search visibility?
Internal links are how a crawler finds the rest of your site and works out how your pages relate. Google's guidance is that every page you care about should have a link from at least one other page, that links should be standard HTML anchors with an href, and that good anchor text is descriptive, reasonably concise and relevant. Other crawlers have no reason to work differently, but that is our inference, not documentation.
A useful test: read each anchor with the sentence around it removed. If it doesn't say what's on the other end, rewrite it.
| Vague anchor | Descriptive anchor |
|---|---|
| Click here | how AI crawlers decide what to index |
| Read more | what structured data a domain needs before launch |
| This post | why AI can't read your parked domain |
What does the 30-day plan look like?
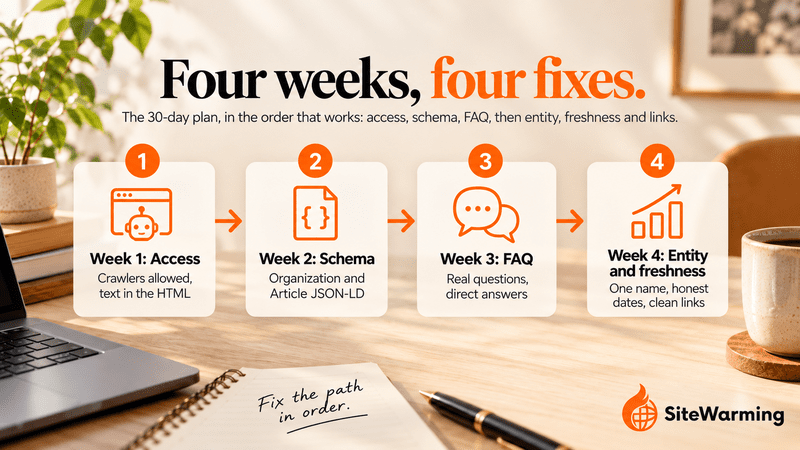
The plan moves from the technical to the editorial, because a page that can't be fetched gains nothing from better schema. Do the weeks in order.
| Week | Focus | What to do | Done when |
|---|---|---|---|
| 1 | Access | Run your top five pages through the Rich Results Test. Check robots.txt, your CDN and your security plugin. Confirm the page text is in the HTML source | Search bots can reach the pages and the text is visible in the source |
| 2 | Schema | Add Organization schema to the home page and Article schema to your key posts, with author and dates | The Schema Markup Validator shows no errors and the markup matches the page |
| 3 | FAQ | Pick three to five real questions for each key page, add a visible FAQ and matching FAQPage markup | Every answer stands alone in two or three sentences |
| 4 | Entity, freshness and links | Standardize your name and description, update dateModified where content changed, add a "checked on" line, fix orphan pages and vague anchors | One name everywhere, honest dates, and every key page linked from another |
Measure it, or you won't know whether it worked. Before week 1, ask ChatGPT with search turned on and Perplexity five questions your site should answer, and write down the date, the exact prompt and whether your domain appears among the cited sources. Repeat at day 30. OpenAI says ChatGPT adds utm_source=chatgpt.com to referral links, so your analytics can show those visits. No vendor publishes how long changes take to appear, and a single test is an anecdote, so treat the result as a signal, not a verdict.
Is your site blacklisted by AI search?
For an ordinary site, no documented blacklist exists. What is documented is eligibility: Google says a page has to be indexed and eligible to be shown in Search with a snippet to be used in its AI features. What is also documented is that nothing is guaranteed. Google's essentials page says following its guidelines doesn't guarantee that a page is crawled, indexed or served.
So this plan raises your odds; it doesn't promise a citation. Our view is that the gap between ignored and cited is mostly mechanical, which is why it is fixable: AI search engines cite what they can read clearly, and the six failures are all ways of not being clear. A site with nothing readable leaves nothing for a system to work from. See also Content Is Memory. If you haven't built yet, Visibility Before Validation and Can a Domain With No Content Show Up in AI Search? cover the earlier problem. For the discipline as a whole, see what generative engine optimization is.
Where SiteWarming fits. Failures 1, 3 and 5 are partly setup work. SiteWarming configures DNS, an HTTPS certificate and hosting for a domain, publishes structured story data and AI-readable FAQs, and, as how it works describes, adds monthly content updates. Your entity name, crawler settings and internal links stay your decisions. What is SiteWarming explains the idea, and you can start free.
Frequently asked questions
Why does AI search ignore my website?
Usually because it can't read the site, not because the content is poor. The common causes are no structured data, inconsistent names, stale or missing dates, blocked crawlers, no question-and-answer structure and unclear internal links. Work through them in the order of the 30-day plan, starting with crawler access.
Is AI search penalizing my site?
No documented blacklist exists for ordinary sites. Google says a page must be indexed and eligible to be shown with a snippet to appear in its AI features, and that following its guidelines doesn't guarantee crawling, indexing or serving. Being ignored is almost always a readability or access problem.
Does schema markup help AI search?
It can help, but it isn't required. Google says no special schema.org markup is needed to appear in AI Overviews or AI Mode, while Search Engine Land reported in March 2025 that Microsoft's Fabrice Canel said Microsoft uses schema to help its LLMs. We add it because it's cheap and removes ambiguity.
Does FAQ schema still work after Google ended FAQ rich results?
Google stopped showing FAQ rich results starting May 7, 2026, so the markup no longer earns that display. We still pair a visible FAQ with FAQPage markup because it accurately describes the page. No vendor documents an AI-search benefit, so treat any benefit as our view.
If I block GPTBot, will ChatGPT stop citing my site?
Not necessarily. OpenAI documents GPTBot as its training crawler and OAI-SearchBot as the crawler for ChatGPT search, and each is controlled separately in robots.txt. To be cited in ChatGPT search, allow OAI-SearchBot.
How often should I update content for AI search?
No vendor documents a schedule. Update a page when its facts change, change dateModified only when the content really did change, and add a "checked on" line to evergreen pages so readers and machines can see when the facts were last verified.
How long until AI search picks up my changes?
No timeline is published for discovery. The only documented figure is for access rules: Perplexity says robots.txt changes may take up to 24 hours to be reflected. Run your before-and-after test at day 30 and treat the result as a signal.
How can I check whether AI search can read my site?
Run four checks: paste the page into the Rich Results Test and the Schema Markup Validator, view the page source for a sentence from the page, open yourdomain.com/robots.txt for Disallow lines, and ask ChatGPT with search on and Perplexity a question your page answers to see whether you're cited.
Related reading
- How AI crawlers decide what to index and what to skip: the bot-by-bot table behind failure 4.
- A beginner's guide to a machine-readable website: the allow-list audit for your own pages.
- Can a domain with no content show up in AI search?: the earlier problem, for domains with nothing on them.
- How to get your site into ChatGPT and Perplexity answers: the step-by-step citation playbook.
- Schema markup for small websites: what to add, what's retired and how to add it.
- How AI search engines decide which domains to trust: the trust signals that sit on top of readability.
Share this article
Ready to Transform Your Domain Portfolio?
Start building real value with your domain investments today.