How AI Crawlers Decide What to Index (And What They Skip)
 Bret Siers
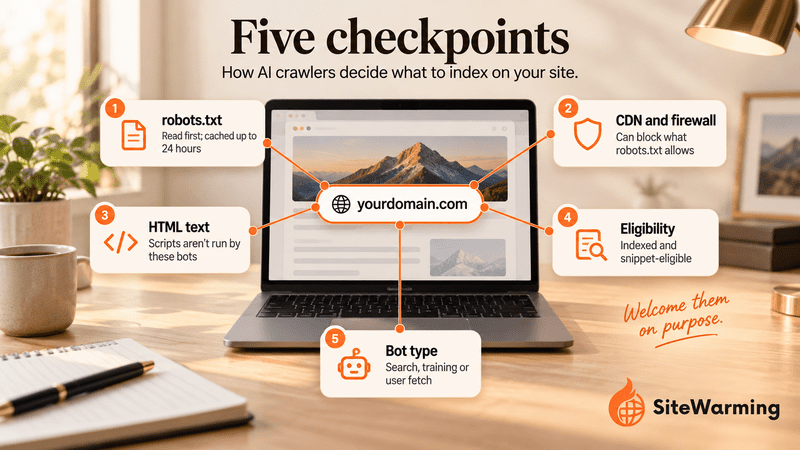
No AI company publishes how its crawler picks pages, but three gates are documented. A bot must be let in by robots.txt and your CDN, find your text in the HTML it fetches, and reach a page eligible to be kept. Search, training and user-fetch bots follow different rules.
By Bret Siers, founder of SiteWarming. Bot names, settings and dates in this guide were checked on October 9, 2026.
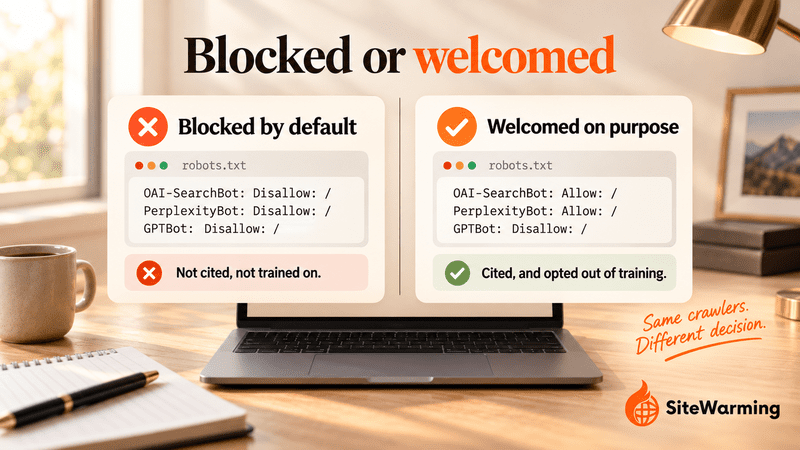
A domain owner turned on Cloudflare's "block AI scrapers" option. It was one checkbox, it took a few seconds, and it felt protective. They didn't want their content used without attribution.
Six months later they searched Perplexity for their own services, using the exact specialty their site covered in more depth than any other. No answer mentioned them. They asked a competitor in a forum thread how they got into Perplexity answers, and the competitor didn't understand the question. They had never blocked AI crawlers.
By the owner's account, the checkbox was the only difference between the two sites. Content quality, authority and history weren't. Whether or not that was the whole story, the lesson holds: an access decision made in two seconds can decide whether anything else you do is read. This guide explains how those decisions work, bot by bot, so you can make them on purpose. For the wider checklist, see the beginner's guide to making your website machine-readable, and for the step-by-step citation playbook, see how to get your site into ChatGPT and Perplexity answers.
What are AI crawlers, and which ones matter?
An AI crawler is an automated program that fetches web pages on behalf of an AI company. The company uses what it fetches in one of three ways: to train a model, to build a search index that an AI answer engine draws on, or to answer one person's question in real time. Those three jobs follow different rules, and most mistakes come from treating them as one.
| Bot | Operator | Job | What the operator documents |
|---|---|---|---|
| OAI-SearchBot | OpenAI | Search | Surfaces sites in ChatGPT search. Sites that opt out "will not be shown in ChatGPT search answers", though they can still appear as navigational links |
| GPTBot | OpenAI | Training | Crawls content that may be used to train OpenAI's models. Disallowing it signals that your content shouldn't be used for training |
| ChatGPT-User | OpenAI | User-initiated fetch | Used when a person asks ChatGPT or a custom GPT something. OpenAI says robots.txt rules may not apply |
| Claude-SearchBot | Anthropic | Search | Analyzes content to improve search results. Blocking it may reduce your visibility in them |
| ClaudeBot | Anthropic | Training | Collects web content that could contribute to model training. Supports the Crawl-delay extension |
| Claude-User | Anthropic | User-initiated fetch | Fetches pages when a person asks Claude a question. Blocking it prevents retrieval in response to a user query |
| PerplexityBot | Perplexity | Search | Surfaces and links sites in Perplexity results. Perplexity says it isn't used to crawl content for AI foundation models |
| Perplexity-User | Perplexity | User-initiated fetch | Visits a page when a person asks a question. Perplexity says it generally ignores robots.txt, because a user requested the fetch |
| Google-Extended | A robots.txt token, not a crawler | Controls whether content Google crawls is used for Gemini training and grounding. Google says it doesn't affect Search inclusion or ranking | |
| CCBot | Common Crawl | Open archive | Builds a free, open repository of web data that anyone can download and analyze |
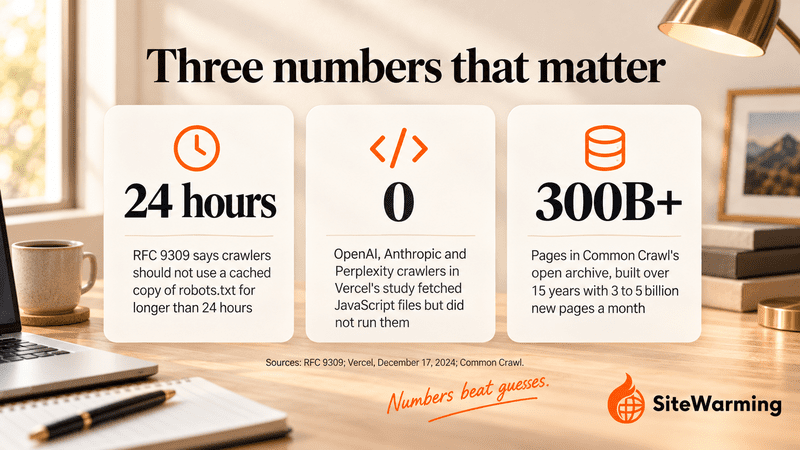
Two rows trip people up. GPTBot is not ChatGPT's search crawler, which is OAI-SearchBot, and Google-Extended is not a crawler at all: Google describes it as "a standalone product token" with no separate user agent string. Common Crawl is a nonprofit whose archive holds over 300 billion pages spanning 15 years, with 3 to 5 billion new pages added each month, which is why blocking CCBot is a separate decision from blocking any one AI company.
How do AI crawlers decide what to crawl and index?
No AI company publishes a ranking formula for crawling, and a guide that claims to list "the signals" is partly guessing, including earlier versions of this one. What is documented is three gates. A page has to pass all three before it can be quoted.
- Is the bot allowed in? Robots.txt is the first gate. RFC 9309, the standard behind it, says the file must sit at /robots.txt, that crawlers should not use a cached copy for more than 24 hours, and that a crawler must assume everything is disallowed if the file can't be reached because of a server or network error. Your CDN or firewall is a second layer: it can block a bot that your robots.txt welcomes.
- Can the bot read the text? Vercel's measurements, published December 17, 2024, found that none of the major AI crawlers it measured render JavaScript. OpenAI's, Anthropic's and Perplexity's crawlers download JavaScript files but don't run them, so text that a script writes into the page doesn't exist for them. Gemini and AppleBot do render JavaScript. This is a snapshot from 2024, so retest your own pages.
- Is the page eligible to be kept and shown? Google says that to appear as a supporting link in AI Overviews or AI Mode, a page must be indexed and eligible to appear in Search with a snippet, with no additional technical requirements. For ChatGPT search, OpenAI's rule is access: you must allow OAI-SearchBot, and placement isn't guaranteed. Perplexity says to allow PerplexityBot if you want to appear in its results.
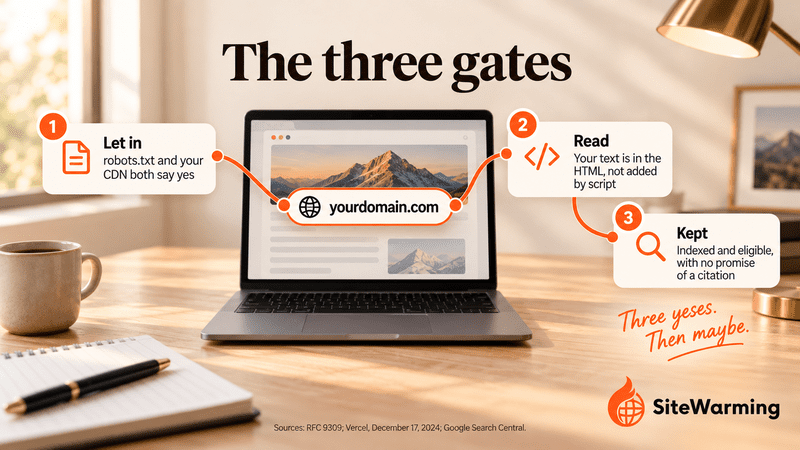
Beyond those gates, the selection rules are private. Whether a page that passes all three is then chosen for an answer depends on the engine's ranking, which nobody outside the company can see. That is why this guide stays on the parts you control. For the trust signals that sit on top of access, see how AI search engines decide which domains to trust.
What do AI crawlers look for on a page?
Vendors haven't published ranked criteria, so treat this as practice, not rules. The table separates what a vendor documents from what is our view.
| Signal | Documented? | What we do |
|---|---|---|
| Your answer is in the server-rendered HTML | Yes. Vercel, December 17, 2024 | Put every answer in the HTML, and search the page source for a distinctive sentence to confirm |
| The page is indexed and snippet-eligible | Yes, for Google's AI features, per Google | Check indexing in Search Console, and don't add nosnippet to pages you want quoted |
| Special structured data | No. Google says there's no special schema.org markup to add for its AI features | We still add Organization and Article markup because it states plain facts; see schema markup for small websites |
| One clear topic per page | No published rule | Our view: a page that answers one question is easier to quote whole than one that answers six |
| Real publication and update dates | No published rule for AI crawlers | Our view: show dates that match real edits. They cost nothing and tell a reader how current the page is |
| Enough depth to quote | No published threshold | Our view: if no sentence on the page could stand alone as an answer, a machine has nothing to lift |
What do AI crawlers skip?
Knowing what gets skipped matters as much as knowing what gets kept. A site can publish excellent work and still be skipped for reasons that have nothing to do with the work.
- Pages your rules disallow. A crawler that honors robots.txt won't fetch a disallowed path. It is a closed sign on a fully stocked store. Compliance is voluntary, though: RFC 9309 says the rules are not a form of access authorization.
- Pages your CDN or firewall blocks. A bot can be turned away before it ever asks for robots.txt.
- Text that only a script writes. If the sentence isn't in the HTML the bot downloads, the bot doesn't see it.
- Dark and parked domains. A domain with no content, a default parking page or a coming-soon placeholder gives a crawler nothing to keep. That isn't a penalty; it is absence. See can a domain with no content show up in AI search? and why AI can't read your parked domain.
- Pages that are thin, copied or hard to classify. Our view: these are the likeliest to be dropped whenever anyone filters a crawl. No vendor documents a threshold, so we don't give one.
How should you set up AI crawler access?
Decide by job, not by company. Allow the search bots if you want to be cited, and choose separately whether to opt out of training.
- Decide what you want from each job. Search bots can send you citations. Training bots take content for models. User-fetch bots act when a person asks a question, and some of them ignore robots.txt, so you can't fully control them.
- Write the rules. The sample below is an illustration, not a recommendation: delete any block you don't want.
- Check your CDN. Robots.txt only matters if the bot reaches your server. Cloudflare's July 1, 2026 changelog says customers can now manage AI traffic by behavior (Search, Agent and Training), each set to allow, block on all pages, block only on pages that display ads, or not block, instead of a single Block AI bots toggle. From September 15, 2026, new domains onboarding to Cloudflare get defaults that block Training and Agent bots on pages that display ads and keep Search allowed. Dashboards change, so read your own rather than trusting a screenshot, including ours.
- Wait about 24 hours. OpenAI says it can take about 24 hours from a robots.txt update for its systems to adjust, and Perplexity says changes may take up to 24 hours.
# Search bots: allow, so your pages can be cited
User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

# Training bots: block only if you want to opt out of training
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: Google-Extended
Disallow: /
Three notes on that sample. Disallowing Google-Extended doesn't touch Googlebot, so Google says your Search inclusion and ranking are unaffected. Disallowing GPTBot doesn't remove you from ChatGPT search, because OAI-SearchBot is a separate bot. And ChatGPT-User, Claude-User and Perplexity-User aren't in the file on purpose: OpenAI says robots.txt rules may not apply to ChatGPT-User, and Perplexity says Perplexity-User generally ignores them.
How can you check what AI crawlers see on your site?
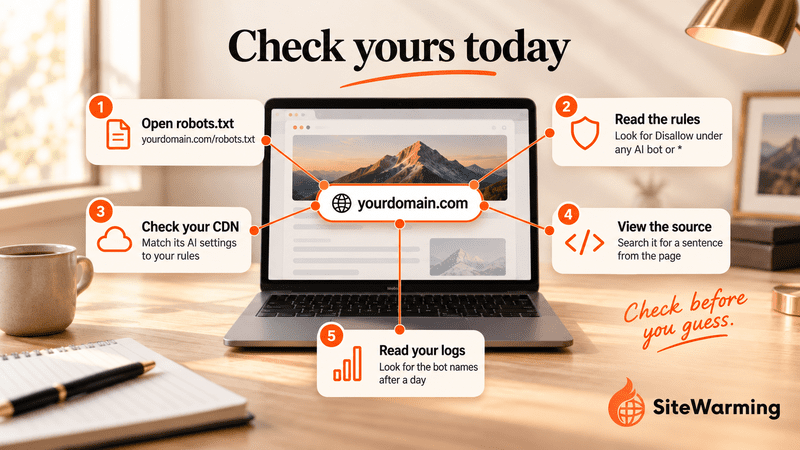
Five checks answer the question for your own domain. They take one sitting.
- Open yourdomain.com/robots.txt in a browser. It should load with a normal response. RFC 9309 says a crawler must assume everything is disallowed when the file can't be reached because of a server or network error.
- Read the rules. Look for a Disallow line under "User-agent: *" or under any AI bot name you didn't mean to block.
- Check your CDN or firewall. Look for a setting named something like AI bots, or for Search, Agent and Training controls, and confirm it matches what your robots.txt says.
- View the page source. Search it for a distinctive sentence from the page. If it isn't there, AI crawlers that don't run JavaScript can't see it.
- Read your server logs after a day. Look for the bot names in the table above. A user-agent string can be faked, and Common Crawl says it knows of crawlers falsely identifying themselves as CCBot, so verify real visits against each operator's published IP list, such as the one Anthropic publishes.
Should you block AI crawlers or welcome them?
Blocking is an understandable instinct. AI companies have built commercial products on web content, and site owners have fair questions about that. In our view the industry hasn't answered them honestly yet. The case for blocking has numbers behind it: in a July 1, 2025 post, Cloudflare's CEO wrote that, compared with the Google of a decade earlier, it is 750 times more difficult to get traffic from OpenAI and 30,000 times more difficult from Anthropic.
But blocking is not neutral. Block a search bot and you leave the answers where people increasingly look. The domain owner in the opening learned that over six months, and you can check your own file in about a minute. The better question isn't "block or allow?" but "which job am I blocking?", because a training bot and a search bot have opposite effects on your visibility.
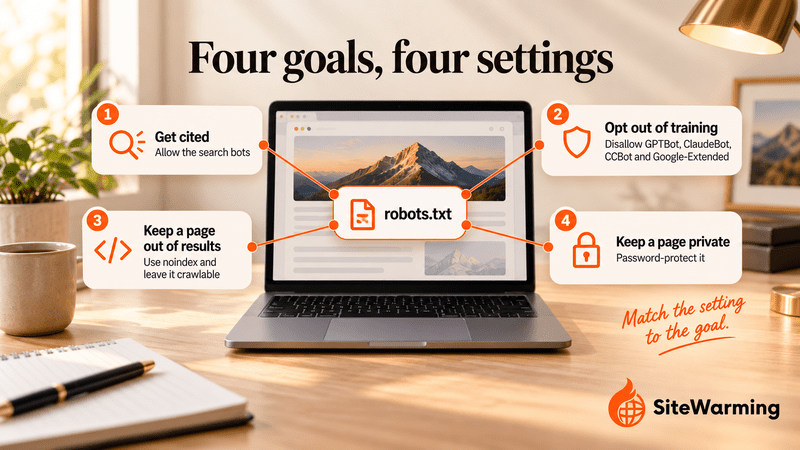
| Your goal | What to do | Why |
|---|---|---|
| Be cited in AI answers | Allow OAI-SearchBot, Claude-SearchBot and PerplexityBot | These are the search bots. OpenAI says sites that opt out of OAI-SearchBot won't be shown in ChatGPT search answers |
| Opt out of model training | Disallow GPTBot, ClaudeBot, CCBot and Google-Extended | OpenAI says disallowing GPTBot signals that content shouldn't be used for training, and Google says Google-Extended doesn't affect Search |
| Keep a page out of results | Add a noindex tag and leave the page crawlable | OpenAI says a disallowed page can still surface as a link and title, and a crawler can read a noindex tag only if it may crawl the page |
| Keep a page private | Password-protect it | Google says robots.txt cannot enforce crawler behavior |
Welcoming crawlers on your terms leads to citation. Blocking everything leads to disappearing. The difference is a deliberate decision, not a default.
What does a domain with no content look like to an AI crawler?
A parked domain, an empty domain and a coming-soon page look the same to a crawler: nothing to read. The bot can be welcome, the robots.txt can be perfect, and there is still no text to keep. That isn't a penalty. It is the absence of anything to index.
Can a domain with no content show up in AI search? covers what a minimum presence looks like, and what structured data a domain needs before launch covers the markup. Why AI can't read your parked domain explains the parking-page case, and why domain parking isn't neutral explains why leaving the default in place is a choice. For the bigger picture of serving people and machines at once, see how to optimize domains for both Google and AI search and the two audiences of every domain. If a page still isn't surfacing after the access checks above, why AI search engines ignore most websites lists the six other failures to look for.
The SiteWarming perspective. Crawler access only matters if there is something to read. A warm site from SiteWarming launches with DNS configuration, an HTTPS certificate, hosting, structured story data, AI-readable FAQs and a protected contact path, so the crawlers you choose to welcome find something clear. That is groundwork, not a guarantee of citation. See how SiteWarming works, what SiteWarming is, or start free.
Frequently asked questions about AI crawlers
Does blocking GPTBot stop ChatGPT from citing me?
No. GPTBot is OpenAI's training crawler, and ChatGPT search relies on OAI-SearchBot, a separate bot. OpenAI says sites that opt out of OAI-SearchBot won't be shown in ChatGPT search answers, so decide the two independently.
What is the difference between GPTBot and OAI-SearchBot?
GPTBot crawls content that may be used to train OpenAI's models. OAI-SearchBot surfaces sites in ChatGPT search results. A third bot, ChatGPT-User, fetches pages when a person asks ChatGPT a question, and OpenAI says robots.txt rules may not apply to it.
Should I block AI crawlers?
That depends on which job you mean. Blocking training bots (GPTBot, ClaudeBot, CCBot and Google-Extended) opts your content out of model training. Blocking search bots (OAI-SearchBot, Claude-SearchBot and PerplexityBot) can remove you from those engines' answers. Our view: a site that wants to be found should allow the search bots, and the training decision is a business choice only you can make.
Is robots.txt enough to block AI crawlers?
No. RFC 9309 says robots.txt rules are not a form of access authorization, and Google says the file cannot enforce crawler behavior. OpenAI and Perplexity also say their user-initiated fetchers may not follow it. For content that must stay private, use a password.
Does Google-Extended affect Google Search?
No. Google says Google-Extended is a robots.txt token that controls whether content is used for Gemini training and grounding, and that it doesn't affect Search inclusion or ranking. For Search, including its AI features, Googlebot's robots.txt rules are the control.
How long does a robots.txt change take to apply?
About 24 hours. OpenAI says it can take about 24 hours for its systems to adjust, Perplexity says up to 24 hours, and RFC 9309 says crawlers should not use a cached copy for longer than that. Check your server logs after a day rather than after an hour.
Do AI crawlers run JavaScript?
Mostly not. Vercel found on December 17, 2024 that the OpenAI, Anthropic and Perplexity crawlers it measured fetch JavaScript files but don't run them, while Gemini and AppleBot do. Put your key text in the HTML and retest, because that is a 2024 snapshot.
Can a page I blocked still appear in AI answers?
It can appear as a link. OpenAI says a disallowed page may still surface as a link and title if its URL comes from a third-party search provider or from other pages. To prevent that, add a noindex tag, which works only if the crawler is allowed to read the page.
Related reading
- The Beginner's Guide to Making Your Website Machine-Readable: the three layers and the 30-minute audit.
- How to Get Your Site Into ChatGPT and Perplexity Answers: the five-step citation playbook.
- Can a Domain With No Content Show Up in AI Search?: what a minimum presence looks like.
- Why AI Search Engines Ignore Most Websites (And What to Do About It): six failures to check.
- What Is GEO? A Guide to Generative Engine Optimization in 2026: the definition and the research behind it.
- Why AI Can't Read Your Parked Domain: the parked-page case.
Share this article
Ready to Transform Your Domain Portfolio?
Start building real value with your domain investments today.